
Bart, co-founder of Media52 and Professor of Journalism oversees IO+, events, and Laio. A journalist at heart, he keeps writing as many stories as possible.
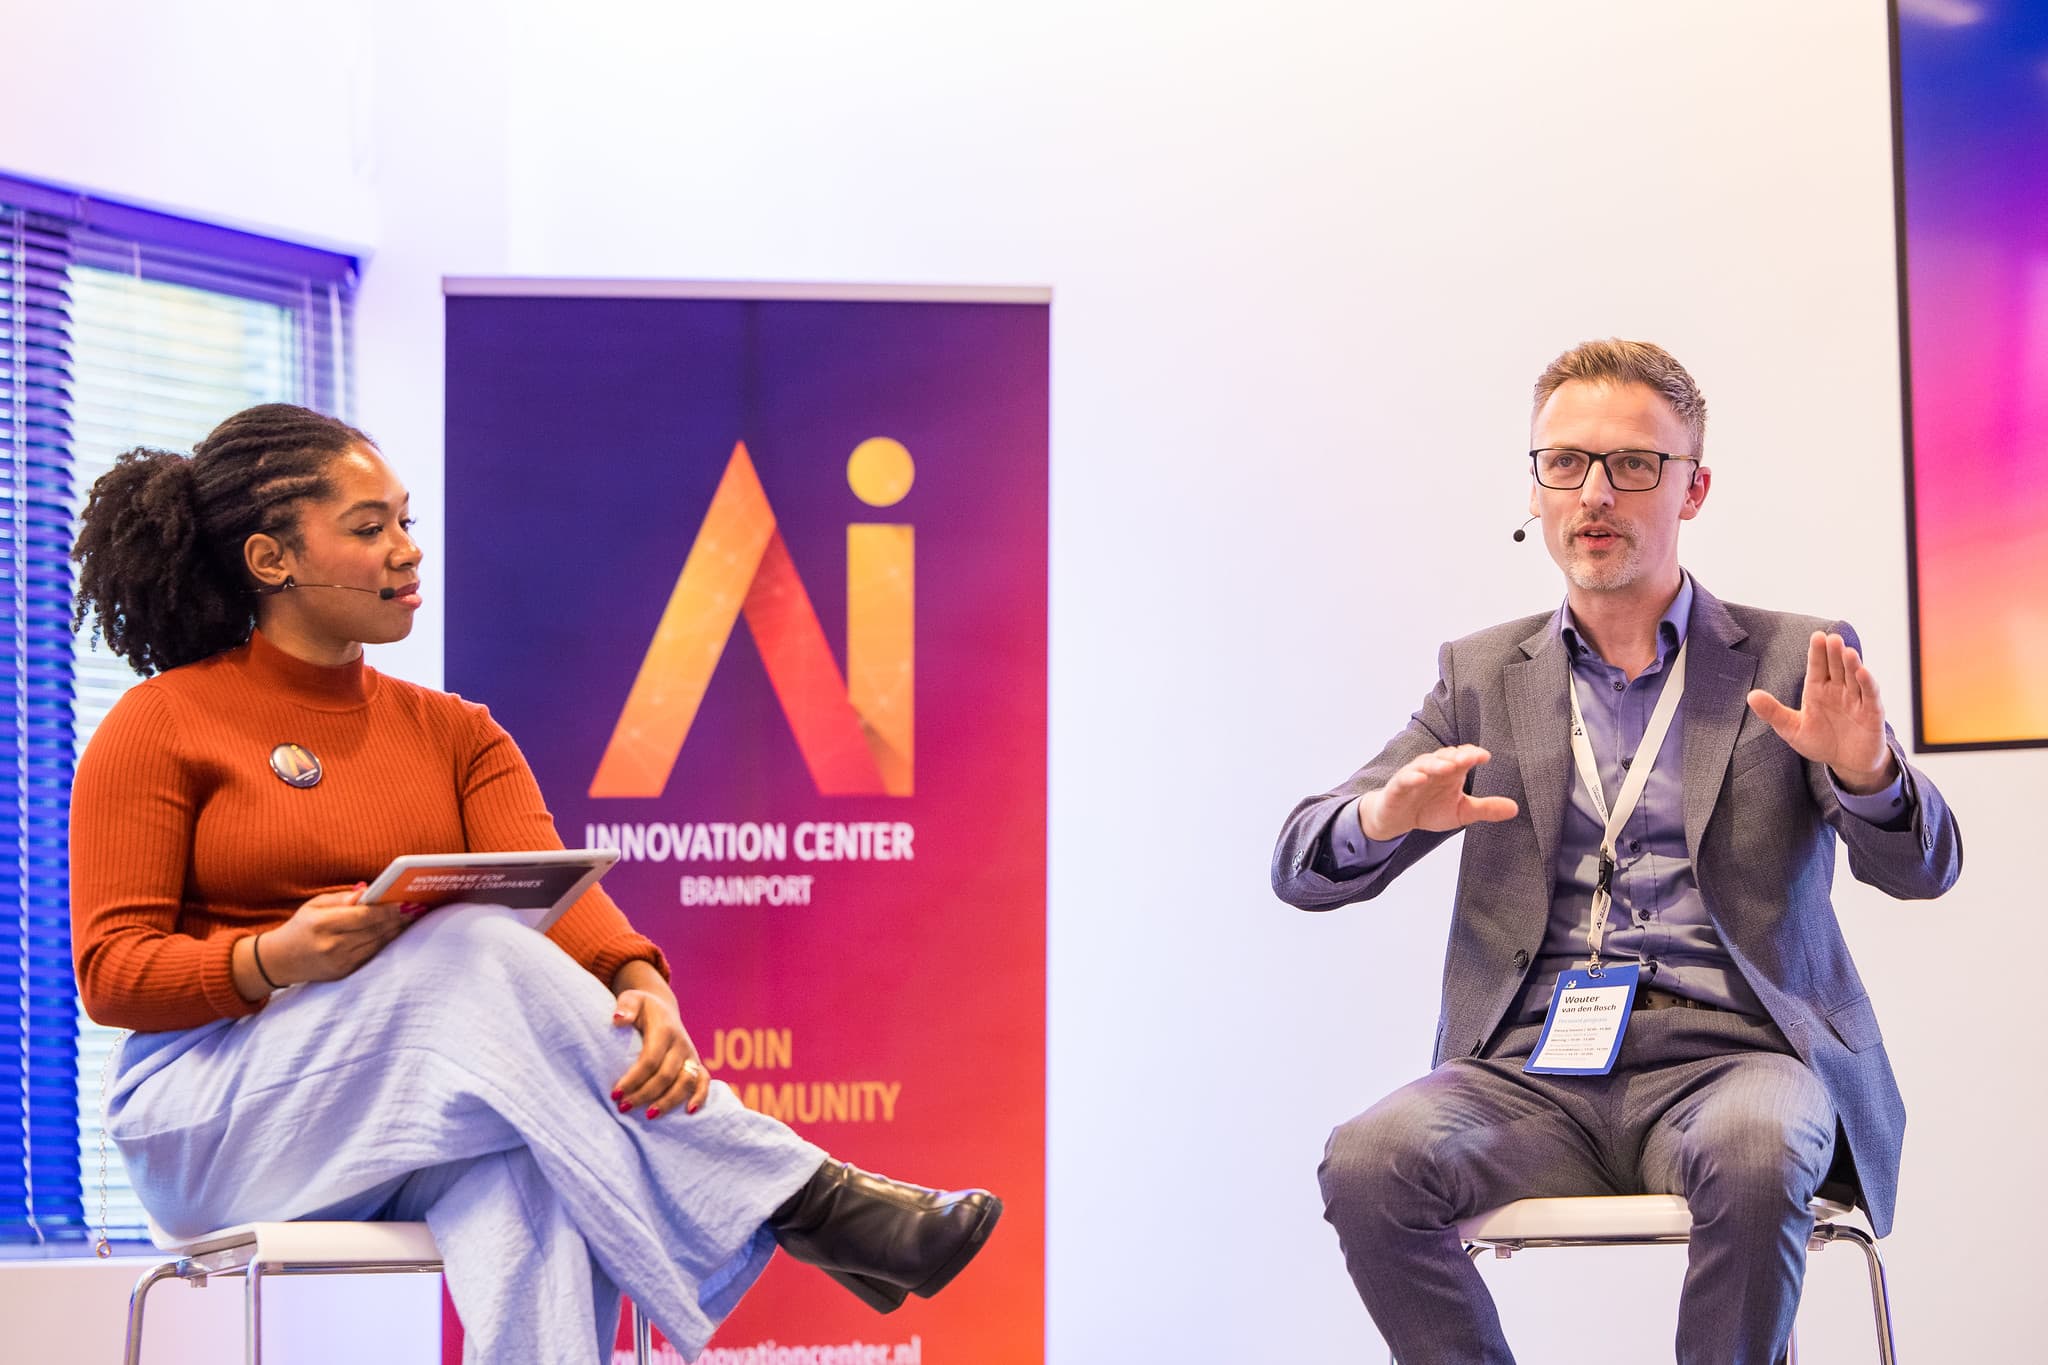
There’s a genre of LinkedIn post that Wouter Van den Bosch knows well. Someone gets an AI coding agent running on a laptop, takes it on a plane and posts a photo of themselves coding in the air. The feat appeals to him, too. But at AI Summit Brainport, imec’s AI product director posed a harder test. What happens when an entire software team needs that agent at the same time?
One developer on a flight can live with a slower response. On Monday morning, dozens of people waiting for the same machine can turn that slowdown into lost working time. Buy enough hardware for the busiest hour and some of it may sit idle overnight. That is part of the bill Van den Bosch asked companies to reckon with during the summit’s AI Implementation Track at Eindhoven’s Evoluon on November 12.
What the GPU does after everyone goes home
A year ago, Van den Bosch recalled, companies he interviewed rarely worried about the cost of tokens, the chunks of text models process and generate. The conversation has changed as coding assistants have spread and companies have put language models inside their own products. Every additional customer who uses an AI feature can add to the bill. And as that bill grows, so does the temptation to buy or rent GPUs and run the models in-house.
Imec’s aistack team put that idea to the test. It gave 64 coding tasks to models running on setups ranging from a single GPU to multi-GPU servers and commercial services. The smaller model that fit on one GPU solved roughly a third of the tasks. The commercial reference model solved 40. A large model with openly available weights could match that score, but it needed a server with eight Nvidia B200 GPUs in the setup tested.
Then there is the question of how many hours those GPUs spend working. A cloud provider can serve customers across time zones. A company hosting a tool for its own staff may see demand bunch up during office hours. For the setups imec tested, buying and renting hardware came out in roughly the same cost range once actual use was factored in. An estimate based on peak demand alone would miss the hours the equipment spends waiting.
The software around the model can change the bill
“At some point we did a test on just replacing the harness on a large language model,” Van den Bosch said. The harness is the software that lets a model read and edit files, run tests and decide which information to feed back to the model as it works. Those decisions affect how much text the model processes on its way to an answer.
In one comparison, two harnesses running the same GLM model solved 33 and 32 of 64 coding tasks respectively. The first processed about 192 million input tokens. The second used about 480 million. Van den Bosch warned that the best combination can change within months as both the model and the software around it evolve.
An audience member brought the discussion back to the workplace. Their organization was paying for tools and training, but how could it tell what it was getting in return? Van den Bosch’s starting point was to make usage visible. Find out which departments generate the most tokens, what tasks they spend them on and where the costs are rising. Then test alternatives on the company’s own work and see what they actually get done. A company could start with a coding workflow and keep using a commercial service for the jobs it handles best.
The same question reaches the chip designer
For imec, those measurements also matter several layers down. A coding agent that pauses to browse the web or write a file can leave an expensive GPU waiting while the CPU does the work. The pattern matters to an engineer deciding how much room to give memory, how much to devote to computation and how to move data between chips.
Van den Bosch pointed to companies including Axelera AI, NXP and imec spin-off Vertical Compute as examples of the expertise Europe could bring together. He wants chipmakers, system builders and AI developers in the same room, comparing what their components do well with what future models will need. He also sees a financing gap when those combinations have to be built and brought to market at scale.
The AI team opening its monthly invoice and the chip designer committing to a roadmap years in advance face different deadlines. Both need to know what the software does once people start using it. The laptop on the plane proves the agent can run. Monday morning reveals how much work it can do, how many people it can serve and what that will cost.